Self-Training for Content-Aware Video Quality Enhancement in HTTP Adaptive Streaming

Self-Training for Content-Aware Video Quality
Enhancement in HTTP Adaptive Streaming

IEEE Transactions on Broadcasting

[PDF]

Yiying Wei (AAU, Austria), Hadi Amirpour (AAU, Austria),  Wei Zhou (Cardiff University, UK), Wassim Hamidouche (TII, UAE) and Christian Timmerer (AAU, Austria)

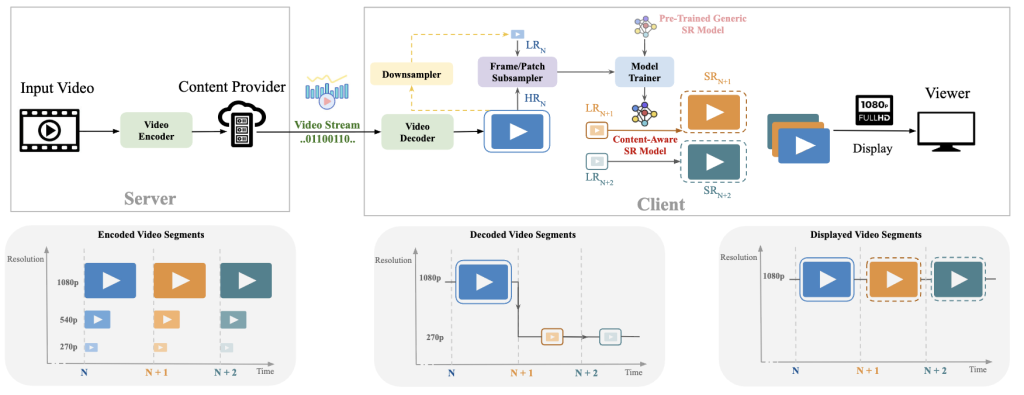
Abstract: Fluctuations in video segment download rates and resolution switching in HTTP Adaptive Streaming (HAS) make it challenging to maintain a consistent Quality of Experience (QoE). However, the impact of such switching is often underestimated, and broadly applicable mitigation strategies remain underexplored. In the past, content-aware approaches have been introduced, using deep neural networks (DNNs) trained on an individual video segment to enhance its quality. These DNNs, transferred as a model stream alongside the video bitstream, allow clients to improve playback quality. However, transferring model streams adds bitrate overhead and additional architectural components, limiting practical use. Furthermore, supporting a wide range of device capabilities with a single DNN is impractical, as it would require device-specific models for each configuration, an approach that becomes unmanageable with increasing device heterogeneity. In this paper, we propose a new self-training method that enables clients to train content-aware video super-resolution (SR) models locally by leveraging previously downloaded high-quality segments. These segments are downscaled and used to train lightweight DNNs, which are then applied to enhance subsequent lower-quality segments. To keep training efficient and real-time, we select only a few predefined frames and extract the most informative patches using a lightweight sampling strategy. Experiments demonstrate that this approach significantly improves visual quality, with average PSNR gains of 1.07 dB (2× upscaling), 0.43 dB (3×), and 0.58 dB (4×) using ESPCN, a lightweight SR approach. To further validate the effectiveness of our approach, we conducted a series of ablation studies to analyze the contributions of individual components. Real-device measurements and end-to-end HAS simulations further show that self-training requires only 2.9–13.0% of a 4-second segment interval on CPU and 1.1–5.3% on GPU across tested mobile devices, while improving VMAF/QoE with only marginal additional rebuffering compared with generic SR.
Posted in ATHENA | Comments Off on Self-Training for Content-Aware Video Quality Enhancement in HTTP Adaptive Streaming

DRLM: Deep Reinforcement Learning-Based LLM Query Orchestration in Edge Environments

DRLM: Deep Reinforcement Learning-Based LLM Query Orchestration in Edge Environments

Reza Farahani (TU Wien, Austria), Zoha Azimi (AAU, Austria), Mario Colosi (University of Messina, Italy), Lauri Lovén (University of Oulu, Finland), Christian Timmerer (AAU, Austria), Schahram Dustdar (TU Wien, Austria)

IEEE Global Communications Conference (GLOBECOM)

7 – 11 December 2026

Macau S.A.R., China

Large language model (LLM) services increasingly process heterogeneous queries with diverse latency, accuracy, and resource requirements. While edge deployment reduces response time, the heterogeneity of devices and the diversity of model families, parameter scales, and quantization levels make efficient LLM query orchestration challenging. This paper introduces DRLM, a Deep Reinforcement Learning-based LLM query orchestration framework in edge environments. DRLM integrates two lightweight predictors: (i) a class-conditioned quality estimator that maps queries to semantic categories and infers model performance, and (ii) a feature-driven latency predictor that estimates inference time across model-device configurations. These predictions, combined with system state (resource utilization and queue dynamics), feed a factorized Proximal Policy Optimization (PPO) agent that performs state-aware orchestration decisions. To enable data-driven orchestration, we construct a large-scale benchmarking dataset with 223 835 measurements spanning 1258 queries, 6 query classes, 8 model families (32 deployed instances), 5 quantization levels, and heterogeneous edge devices. Evaluation on a realistic 64-node edge cluster and comparison with three baselines and two state-of-the-art methods show that DRLM reduces inference latency by up to 51 % and queuing delay by up to 67 %, while incurring at most 8 % accuracy loss. DRLM further improves latency under increasing workloads up to 61.4 %, demonstrating robust and stable orchestration.

Posted in ATHENA | Comments Off on DRLM: Deep Reinforcement Learning-Based LLM Query Orchestration in Edge Environments

VCA-FFMPEG: A FFmpeg Filter for Video Complexity Analysis

VCA-FFMPEG: A FFmpeg Filter for Video Complexity Analysis

34th ACM International Conference on Multimedia 2026 (ACM MM 2026)

10–14 November 2026

Rio de Janeiro, Brazil

[PDF]

 Hadi Amirpour (AAU, Austria),  Mykyta Skipenko (AAU, Austria), and Christian Timmerer (AAU, Austria)

Abstract:

VCA is a widely used open-source framework for estimating spatial and temporal video complexity features for applications such as per-title encoding, bitrate ladder generation, and content-adaptive streaming. However, the original VCA workflow requires videos to be preprocessed into raw formats such as YUV or Y4M before analysis, introducing additional decoding, conversion, storage, and pipeline overhead. Moreover, the standalone implementation has limited portability across platforms, devices, and heterogeneous multimedia processing systems.

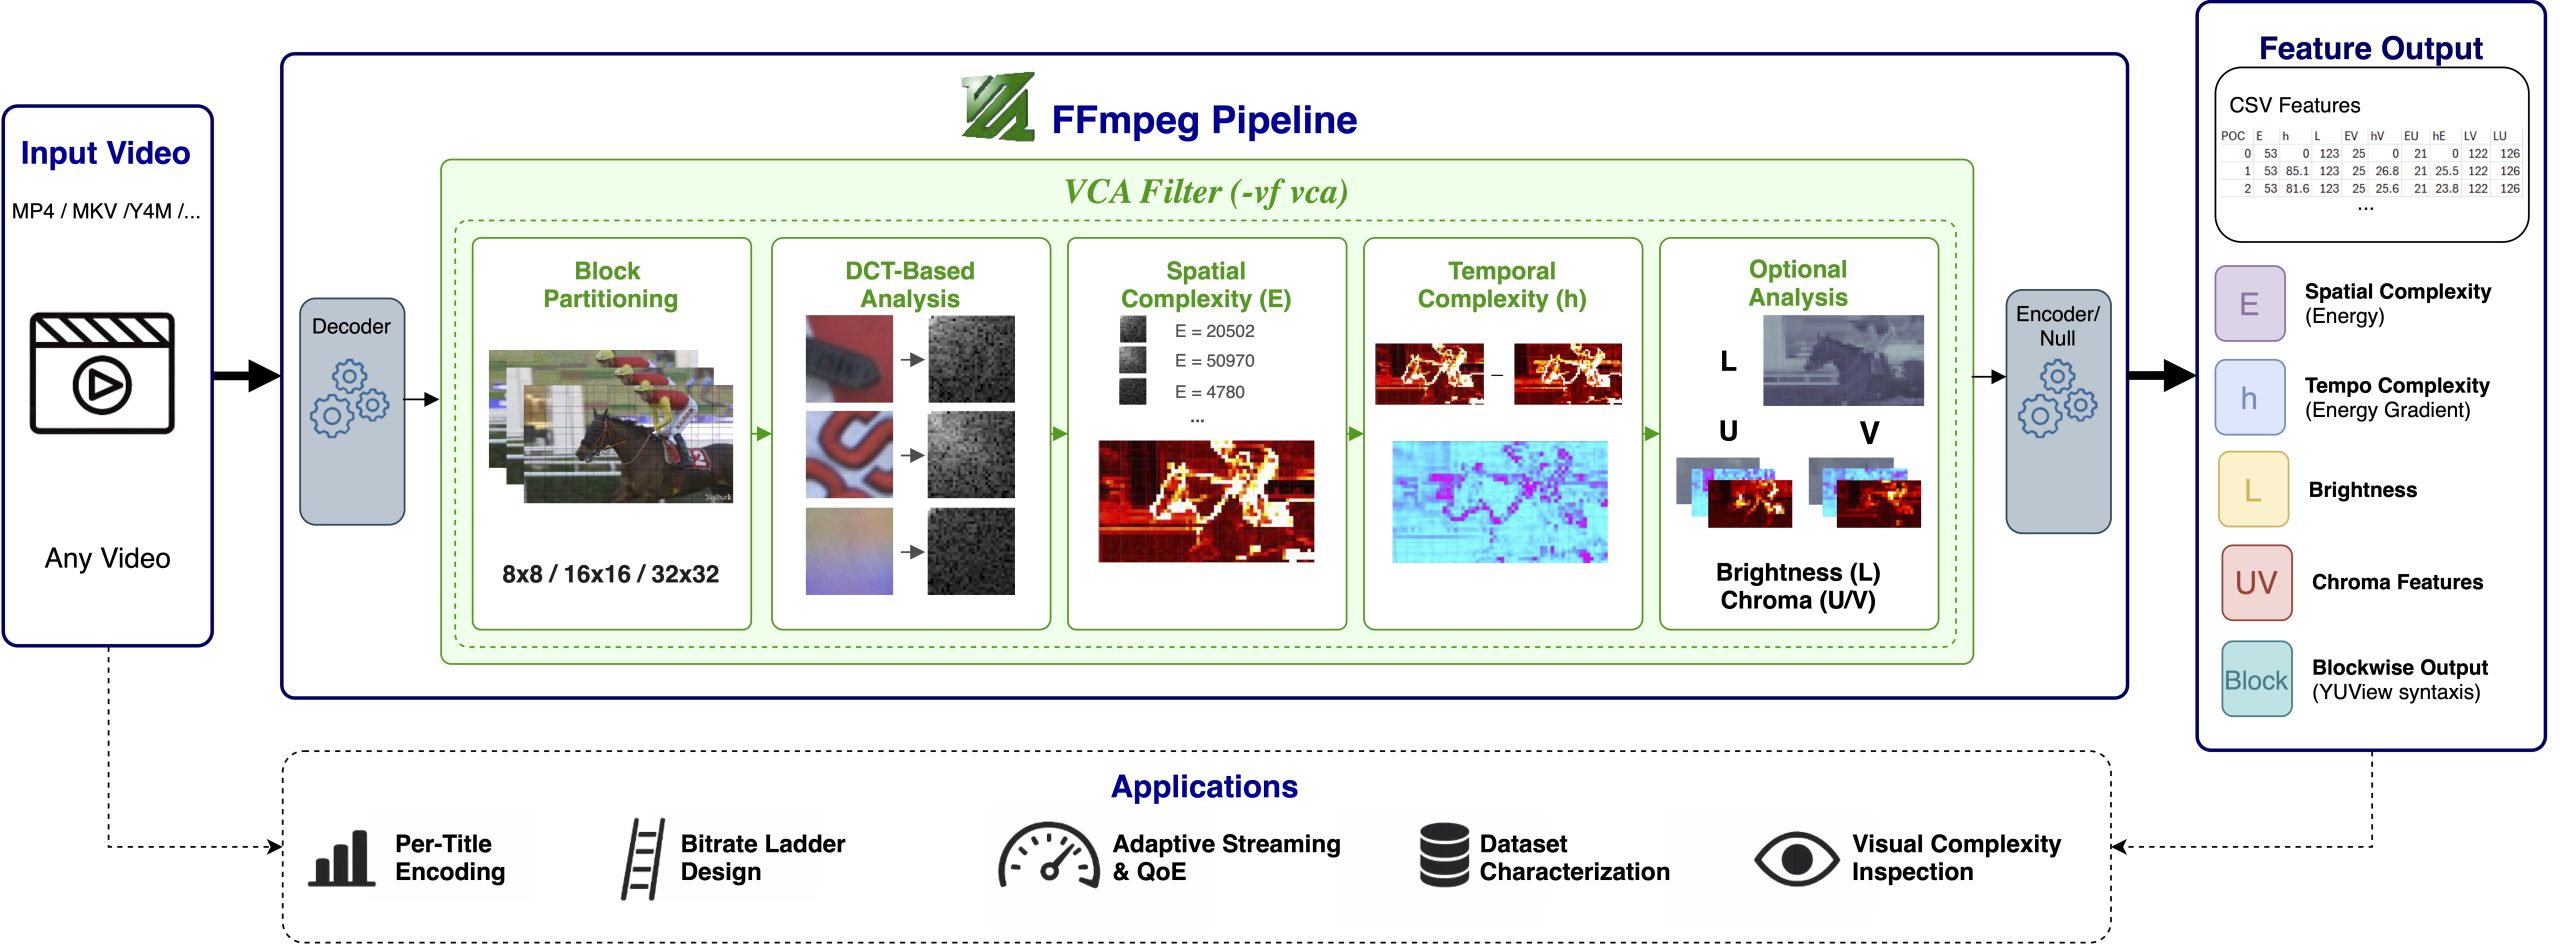
In this paper, we present VCA-FFmpeg, an open-source integration of VCA as a native filter inside the FFmpeg multimedia framework. By embedding VCA directly into FFmpeg’s filtering pipeline, the proposed system removes the need for external preprocessing and intermediate format conversion, enabling complexity analysis on virtually any video format supported by FFmpeg. The integration allows users to extract spatial, temporal, brightness, and chroma descriptors during standard decoding, transcoding, or filtering operations using a simple command-line interface.

VCA-FFmpeg supports configurable block-based analysis, multi-threaded execution, optional low-pass DCT acceleration, SIMD optimizations, and YUView-compatible block-level visualization. Since FFmpeg is broadly supported across operating systems and hardware platforms, the proposed framework improves portability, usability, and reproducibility compared to standalone VCA. In our runtime evaluation, VCA-FFmpeg processed MP4 input at 462.7 fps, compared with 194.5 fps for the standalone workflow that first converts MP4 to Y4M and then applies VCA. By leveraging FFmpeg’s multimedia ecosystem, VCA-FFmpeg provides an efficient and scalable solution for in-pipeline video complexity feature extraction in multimedia systems, adaptive streaming, and video coding research.

Posted in ATHENA | Comments Off on VCA-FFMPEG: A FFmpeg Filter for Video Complexity Analysis

MoQSplat: Adaptive Progressive Streaming of 3D Gaussian Splatting over MoQ

MoQSplat: Adaptive Progressive Streaming of 3D Gaussian Splatting over MoQ

IEEE International Workshop on Multimedia Signal Processing (MMSP)

September 22 – September 24, 2026

Istanbul, Turkey

[PDF]

Emanuele Artioli (AAU, Austria), Mohammadreza Ghafari (Universit´e de Lorraine, France), Md Tariqul Islam (UNICAMP, Brazi), Farzad Tashtarian (AAU, Austria), Christian Rothenberg (UNICAMP, Brazi), Christian Timmerer (AAU, Austria)

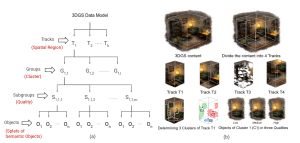
Abstract. 3D Gaussian Splatting (3DGS) delivers photorealistic novel view synthesis by representing scenes as millions of explicit Gaussian primitives. However, transmitting this data efficiently over a network remains a challenge for immersive applications. Realistic scenes can easily exceed several gigabytes, and traditional HTTP Adaptive Streaming over TCP introduces Head-of-Line (HOL) blocking that is ill-suited to the fine-grained, spatially selective delivery of 3DGS content. We propose MoQSplat to map 3DGS content onto the Media over QUIC (MoQ) transport hierarchy. MoQSplat partitions the scene into spatial Tracks, organizes splats into semantically coherent Groups via object-aware spatial clustering, and constructs progressive-quality Subgroups, each mapped to an independent QUIC stream to eliminate spatial HOL blocking. Crucially, MoQSplat features a completely stateless, subscriber-driven adaptation loop. The client selectively requests spatial regions and quality tiers based on live frustum visibility, distance, and foveal centrality. We validate the architecture’s core components by comparing opacity-based and scale-based pruning strategies for Subgroup generation.

Posted in ATHENA | Comments Off on MoQSplat: Adaptive Progressive Streaming of 3D Gaussian Splatting over MoQ

Towards AI-Assisted Sustainable Adaptive Video Streaming Systems: Tutorial and Survey

Towards AI-Assisted Sustainable Adaptive Video Streaming Systems: Tutorial and Survey

Reza Farahani, Zoha Azimi, Christian Timmerer, Radu Prodan

ACM Computing Surveys (CSUR)

Improvements in networking technologies and the steadily increasing number of users, as well as the shift from traditional broadcasting to streaming content over the Internet, have made video applications (Video-on-Demand (VoD) and live streaming) predominant sources of traffic. Recent advances in Artificial Intelligence (AI) and its widespread application in various academic and industrial fields have focused on designing and implementing a variety of video compression and content delivery techniques to improve user Quality of Experience (QoE). However, providing high QoE services results in increased energy consumption and a larger carbon footprint across the service delivery path, extending from the end-user’s device through the network and service infrastructure (e.g., cloud providers). Despite the importance of energy efficiency in video streaming, there is a lack of comprehensive surveys covering state-of-the-art AI techniques and their applications throughout the video streaming lifecycle. Existing surveys typically focus on specific parts, such as video encoding, delivery networks, playback, or quality assessment, without providing a holistic view of the entire lifecycle and its impact on energy consumption and QoE. Motivated by this research gap, this article provides a comprehensive overview of the video streaming lifecycle, content delivery, energy, and Video Quality Assessment (VQA) metrics and models, and AI techniques employed in video streaming. In addition, it conducts an in-depth state-of-the-art analysis of AI-driven approaches for improving the energy efficiency of end-to-end video streaming systems across encoding, delivery, playback, and VQA stages. It further discusses key challenges in AI-assisted streaming, including ethical concerns (privacy, bias, security), deployment barriers (dataset limitations, scalability, inference efficiency), protocol-level latency-computation trade-offs (e.g., QUIC and WebRTC), and the energy implications of Generative AI and semantic streaming.


Posted in ATHENA | Comments Off on Towards AI-Assisted Sustainable Adaptive Video Streaming Systems: Tutorial and Survey

AGSR: Aperture-Guided Super-Resolution for Gaussian Splatting

AGSR: Aperture-Guided Super-Resolution for Gaussian Splatting

Ayman Alkhateeb, Hadi Amirpour, Christian Timmerer

Best Paper Award

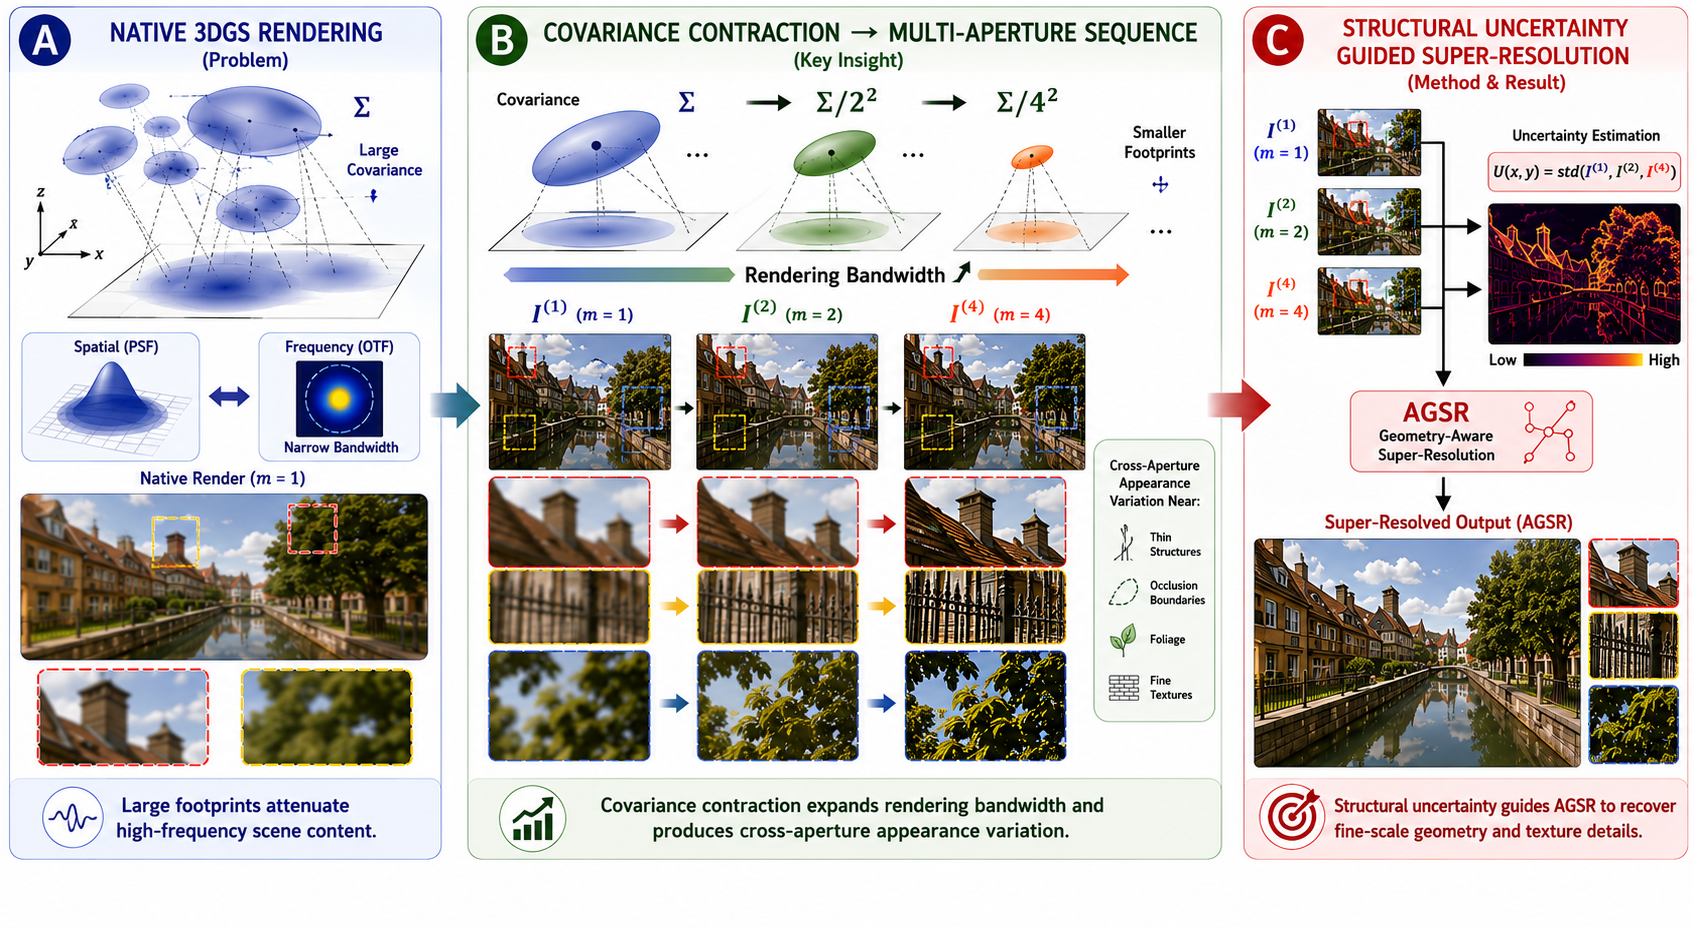
Abstract: 3D Gaussian Splatting (3DGS) enables real-time novel view synthesis, but Gaussian rasterization attenuates fine-scale scene structure through the projected covariance of each primitive. We show that contracting projected covariances at inference time reveals recoverable structural cues that remain latent in the learned representation, motivating a multi-aperture rendering framework for super-resolution.
Based on this insight, we propose AGSR (Aperture-Guided Super-Resolution), a lightweight inference-time framework that progressively fuses multi-aperture renderings using uncertainty-guided feature aggregation and geometric conditioning from transmittance and depth cues. AGSR operates as a plug-in enhancement for pre-trained 3DGS models.
Experiments on the Mip-NeRF 360 benchmark show that AGSR outperforms lightweight image-space super-resolution baselines, with gains increasing as the underlying Gaussian representation deteriorates. The results provide empirical evidence that covariance contraction exposes recoverable structural cues attenuated by native Gaussian rasterization. AGSR achieves these improvements while maintaining real-time performance with up to 66K parameters.

Posted in HoloSense | Comments Off on AGSR: Aperture-Guided Super-Resolution for Gaussian Splatting

Wave-Aware Primitive Culling for Scalable Gaussian Wave Splatting

Wave-Aware Primitive Culling for Scalable Gaussian Wave Splatting

Ayman Alkhateeb, Hadi Amirpour, Christian Timmerer

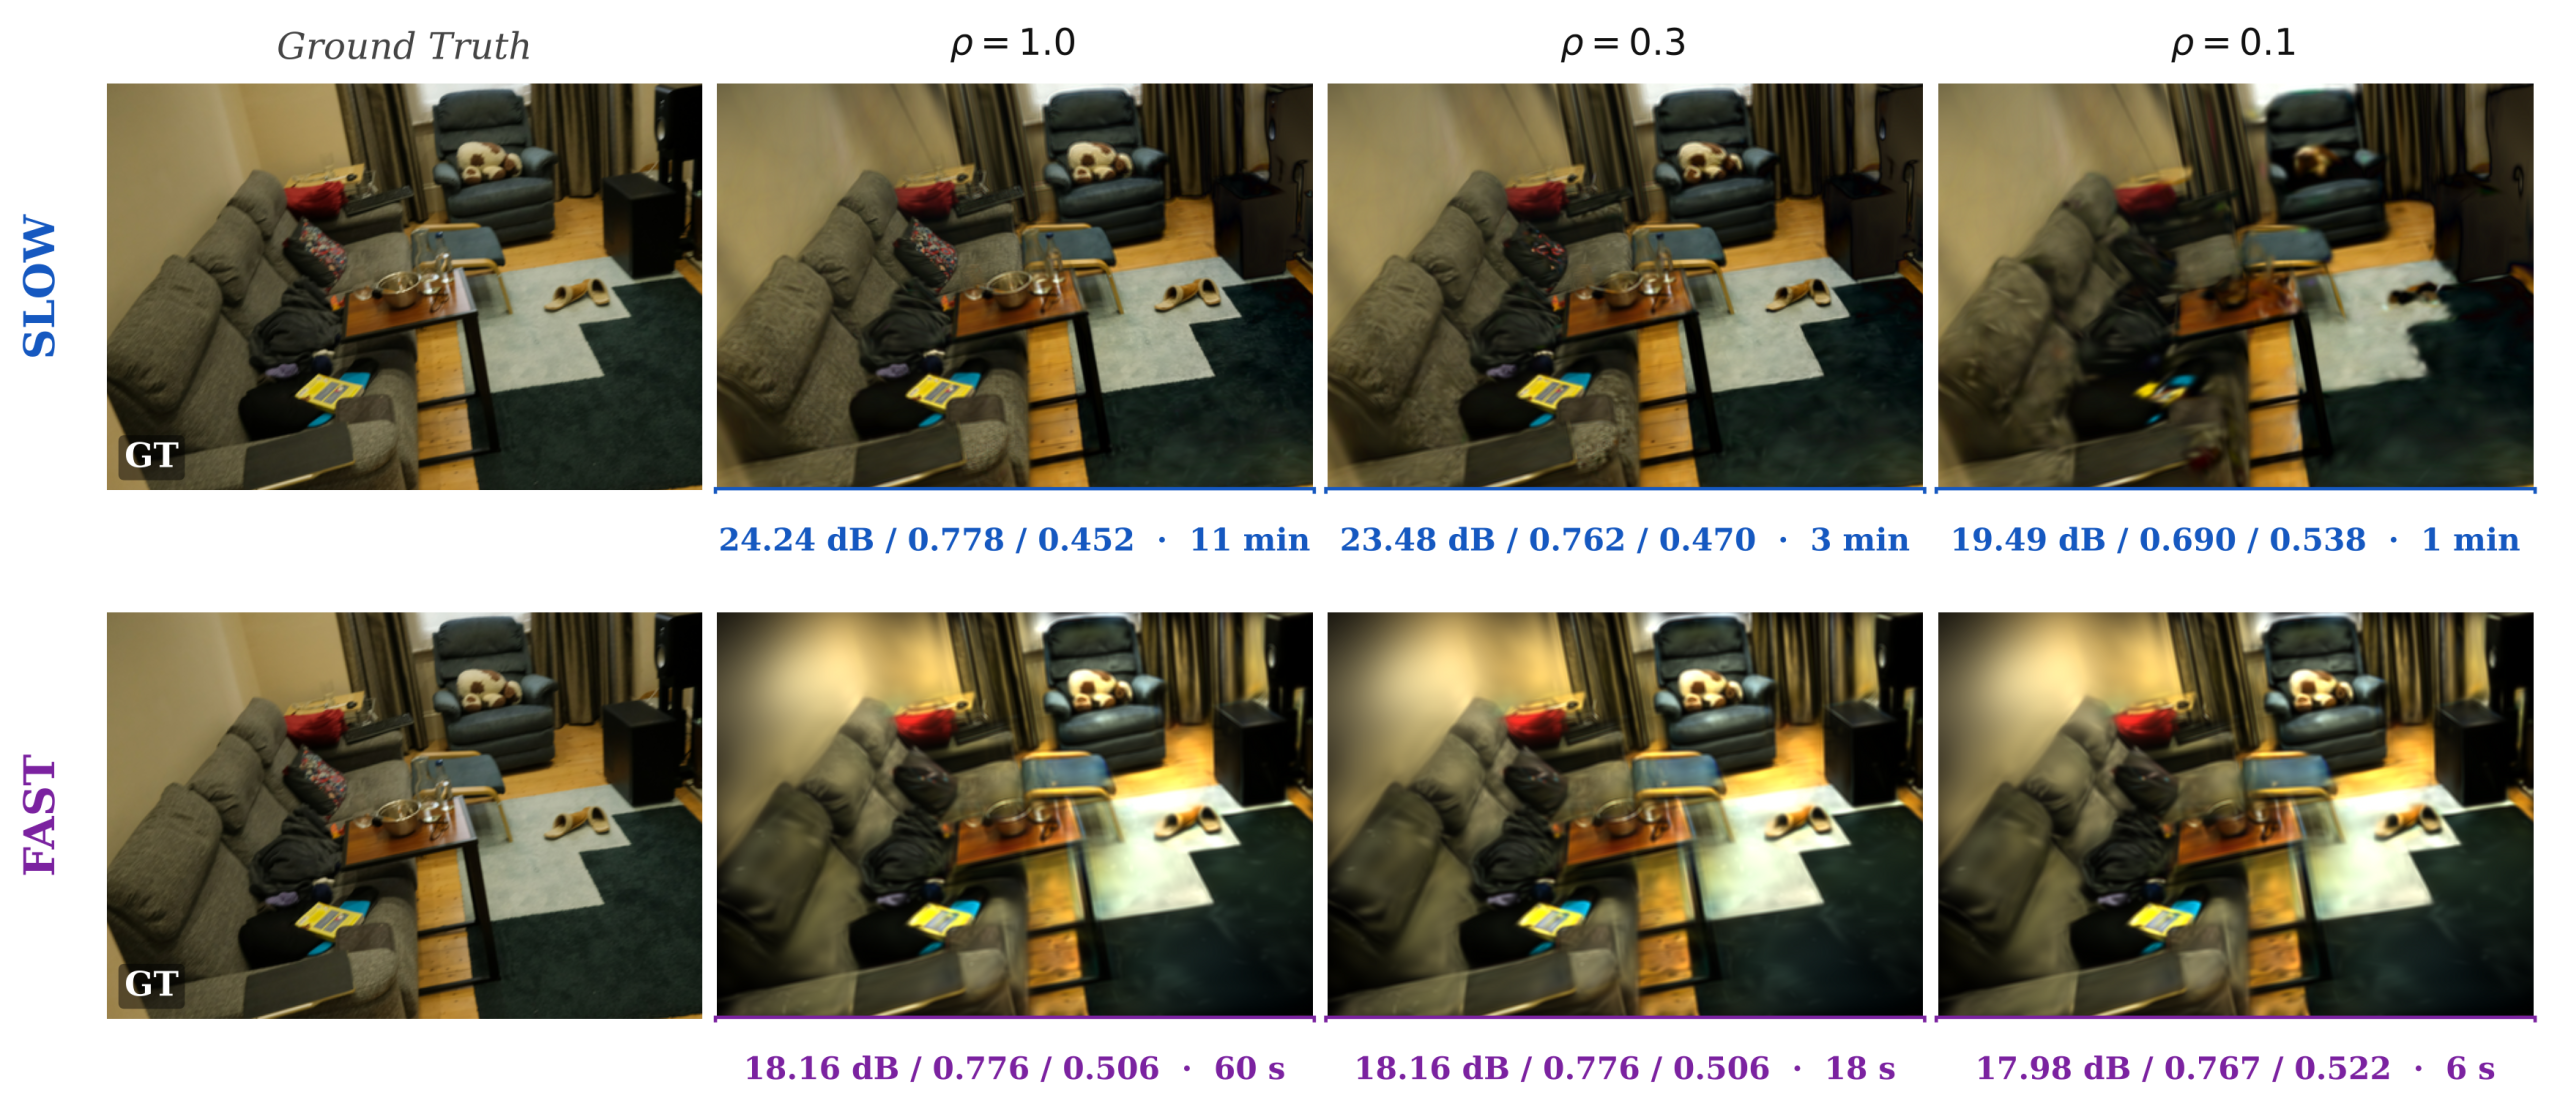
Computer-generated holography (CGH) enables realistic depth perception by reconstructing full optical wavefields, but its practical use is limited by high computational cost. Gaussian Wave Splatting (GWS) represents a promising direction by mapping Gaussian scene primitives directly into complex wavefields, but even its accelerated formulations remain computationally expensive due to the high processing time required for large numbers of primitives. In this work, we present a novel, energy-based culling criterion derived from the angular spectrum formulation of wave propagation to remove redundant primitives in Gaussian Wave Splatting (GWS). Our energy criterion, based on opacity and spatial scale, provides a physics-inspired way to estimate each primitive’s contribution and enables multi-resolution rendering without retraining. Evaluations on the Mip-NeRF 360 dataset show that our criterion effectively isolates the scene’s structural backbone. By discarding up to 70 % of primitives, our method accelerates rendering by 72% in fast additive pipelines with near-lossless reconstruction quality (Delta PSNR <= 0.05 dB compared to the unculled baseline). Furthermore, it achieves a 70% speedup in exact alpha-wave-blending pipelines while preserving high perceptual fidelity, providing a critical step toward real-time neural rendering for holographic displays.

Posted in HoloSense | Comments Off on Wave-Aware Primitive Culling for Scalable Gaussian Wave Splatting