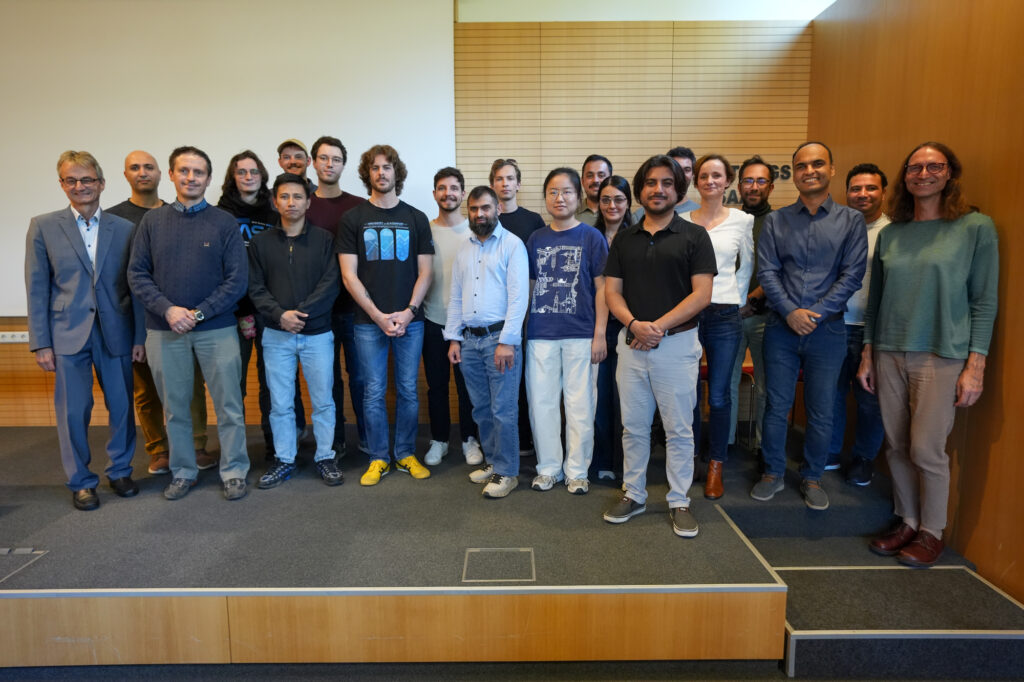
Seven Years of ATHENA: Concluding the Christian Doppler Laboratory

The Christian Doppler (CD) Laboratory ATHENA was established in October 2019 to tackle current and future research and deployment challenges of HTTP Adaptive Streaming (HAS) and emerging streaming methods. After seven years, ATHENA officially concluded on September 30, 2026, and we have submitted our final report to the Christian Doppler Research Association (CDG). Time to look back at the achievements of the third and final phase (years 6 and 7; see ATHENA 5-year blog post here) and at what ATHENA accomplished over its entire lifetime.

CD laboratories conduct application-oriented basic research, promote collaboration between universities and companies, and facilitate technology transfer. They are funded through a public-private partnership between companies and the CDG, which in turn receives public funding from the Austrian federal government. ATHENA was supported by Bitmovin as company partner throughout its entire duration.

The big picture

Video streaming remains by far the dominant application on today’s Internet, which makes every improvement in efficiency, quality, and energy consumption relevant for billions of viewers. ATHENA addressed the entire streaming chain in four work packages: content provisioning (WP-1), content delivery (WP-2), content consumption (WP-3), and end-to-end aspects (WP-4). WP-2 was concluded after the first cohort of PhD students completed their theses, allowing us to focus resources on the remaining work packages in the final phase.

If we had to summarize seven years of research in one sentence, it would be this: the trade-off between content complexity, latency, and Quality of Experience (QoE) is not a law of nature, but largely a consequence of static system design. Two publications illustrate this particularly well. The Video Complexity Analyzer (VCA) (ACM MMSys 2022) made content complexity measurable in real time and enabled content-adaptive encoding even for live streaming. ARTEMIS (USENIX NSDI 2024) showed that dynamically adapting the bitrate ladder during a live session reduces encoding computation by 25%, end-to-end latency by 18%, and simultaneously improves QoE by 11%. In other words, all three dimensions can improve at the same time.

Highlights of the final phase

During years 6 and 7, ATHENA contributed 40 papers, including publications in the IEEE Internet of Things Journal, IEEE Transactions on Circuits and Systems for Video Technology, ACM Transactions on Multimedia Computing, Communications, and Applications, IEEE Journal on Emerging and Selected Topics in Circuits and Systems, and ACM Computing Surveys. Content provisioning (WP-1) produced 22 papers, content consumption (WP-3) 8 papers, and end-to-end aspects (WP-4) 10 papers.

Scientifically, the final phase was characterized by a clear shift towards AI and generative methods:

  • Generative AI for streaming: Conventional codecs transmit every pixel, even where the content could be predicted from context. ELVIS (ACM NOSSDAV 2025) removes less important blocks of each frame at the server and lets a generative in-painting model reconstruct them at the client, improving perceptual quality by up to 11 VMAF points over standard encodings at matched bitrates. GenStream (ACM MM 2025, Brave New Ideas) takes this idea further for human-centric content such as sports: instead of pixels, it transmits skeletal poses, camera parameters, and a 3D background model, from which the client reconstructs the video. In first experiments on figure skating footage, the bitrate dropped from 5.8 Mbps to below 10 kbps, a reduction of more than 99.9%, while preserving natural motion.
  • Immersive media: 3D Gaussian Splatting enables photorealistic scenes for virtual and augmented reality, but its models are large and demanding to render. MoQSplat (IEEE MMSP 2026) delivers such scenes progressively over Media over QUIC, eliminating head-of-line blocking and enabling near-instantaneous startup. TIGAS (ACM MM 2026) targets thin clients such as smartphones, smart TVs, and standalone headsets by rendering remotely and streaming over HTTP/3, achieving a motion-to-photon latency of around 60 ms on regional edge nodes, compared with 120 to 300 ms for low-latency DASH/CMAF baselines. A short survey on QoE modeling for volumetric video streaming (IEEE/IFIP NOMS) complements this work with a taxonomy and open research challenges.
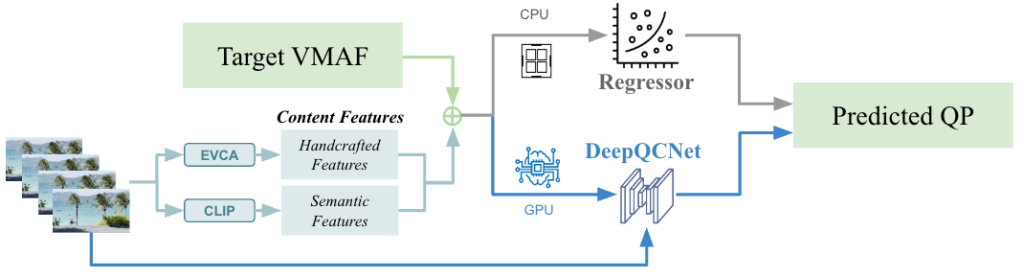
  • Energy- and content-aware encoding: ATHENA continued its sustainability line by making energy a first-class encoding objective. LiveESTR (IEEE JETCAS 2025) constructs quality- and energy-aware bitrate ladders for live streaming in real time, reducing the energy required to prepare representations by 74.6% and decoding energy by 29.7% compared with per-title encoding, at only a 2.1% BD-Rate increase. EcoEncode selects codec and preset based on the expected number of views and content complexity, achieving an average BD-Energy reduction of 66.1% for videos with fewer than 2,000 views. DeepQC predicts the quantization parameter needed to reach a target VMAF directly from the source, without pre-encoding, enabling real-time quality-driven encoding on both CPU and GPU infrastructures.
  • AI-based video enhancement: Content-aware super-resolution can improve low-resolution streams by adapting a neural network to each video, but training is costly. EPS (IEEE TCSVT 2026) uses lightweight DCT-based complexity features to select only informative training patches, discarding between 75% and 92% of them while preserving comparable or even better reconstruction quality. Self-Training (IEEE Transactions on Broadcasting 2026) moves content adaptation entirely to the client: the player fine-tunes a super-resolution model using high-resolution segments already in its buffer, eliminating the need to transmit a separate model stream. Under real network traces, this raised average VMAF from 90.84 to 92.99 and reduced quality oscillations, with a negligible increase in rebuffering.

Technology transfer and patents

Over its lifetime, ATHENA resulted in 24 invention disclosures and 21 patent applications (including provisionals), of which 13 US patents have been granted so far together with our company partner. Topics in the final phase include transport-assisted media selection for Media over QUIC, LLM-guided adaptive bitrate algorithms, generative live streaming, and efficient quality control for video encoding.

Several results have been transferred into Bitmovin products and processes, including CAdViSE, the WISH ABR logic in the Bitmovin Player, CO2 calculation for encodings (via the follow-up project GAIA), and VCA-based improvements of per-title encoding. Bitmovin’s live content-adaptive encoding based on real-time VCA achieved around 14.7% bitrate savings at a negligible quality loss in internal validation.

We also continued our commitment to reproducibility through open source tools and datasets. VCA, for example, is used by the Joint Video Experts Team (JVET).

Events and community

A highlight of the final phase was hosting IEEE VCIP 2025 in Klagenfurt in December 2025. In addition, the ATHENA team organized workshops at ACM CoNEXT (EMS 2026), IEEE ICME (P3DMM 2026), ACM MM, and ACM Mile-High Video 2025, two special sessions at IEEE ICIP 2026, and tutorials at ACM MM 2025 and IEEE ICME 2025.

Awards in the final phase include the Best Student Paper Award at the NAB BEIT Conference 2025, the Best Paper Award and the Multimedia Rising Star Award at IEEE MMSP 2026, a top 25 most downloaded article of the IEEE Signal Processing Society, and elevations to IEEE and ACM Senior Member.

People

The most important outcome of a CD laboratory are the people it trains. In the final phase, Dr. Daniele Lorenzi defended his PhD thesis “QoE- and Energy-aware Content Consumption for HTTP Adaptive Streaming” (July 31, 2025), bringing the total number of PhD graduates to eight. Both postdoctoral scholars completed their habilitation:

The next cohort of PhD students is now in the final stage of their doctoral studies and about to submit their theses (working titles):

  • Emanuele Artioli, “From Pixels to Semantics: Compute-Bandwidth Tradeoff in Next-Generation Video Streaming”
  • Zoha Azimi Ourimi, “AI-Assisted Energy-Efficient HTTP Adaptive Video Streaming”
  • Mohammad Ghasempour, “Content-Adaptive Multimedia Coding and Processing for Energy-Efficient Adaptive Streaming”
  • Kamran Qureshi, “Efficient Encoding Strategies for Immersive and Adaptive Streaming Media Applications”
  • Yiying Wei, “Neural Adaptive Video Representation and Generative Reconstruction for HTTP Adaptive Streaming”

ATHENA alumni now work at universities, research institutions, and companies across Europe and beyond, including the University of Klagenfurt, TU Wien, Fraunhofer FOKUS, Yıldız Teknik Üniversitesi, Qualcomm, and Bitmovin. Dr. Hadi Amirpour is now Assistant Professor (tenure track) at the University of Klagenfurt.

What’s next

ATHENA ends, but the research continues. Many of the threads started in the final phase, from generative AI for streaming to immersive media, will be carried forward under the lead of Dr. Farzad Tashtarian, again in close collaboration with Bitmovin. Stay tuned, we look forward to sharing more early next year! In addition, ATHENA’s methods live on in ongoing follow-up projects such as HoloSense, ForestScope, and DORBINE.

Thank you

Thanks to all current and former ATHENA team members: Samira Afzal, Jesús Aguilar Armijo, Hadi Amirpour, Emanuele Artioli, Zoha Azimi Ourimi, Christian Bauer, Alexis Boniface, Ekrem Çetinkaya, Seungmi Choi, Thomas Curry, Reza Ebrahimi, Filipp Eder, Alireza Erfanian, Reza Farahani, Philipp Fößl, Vanessa Fröhlich, Kassian Fugger, Mohammadreza Ghafari, Mohammad Ghanbari (late), Milad Ghanbari, Mohammad Ghasempour, Afshin Gholami, Daniel Glantschnig, Vladislav Golovatenko, Gabriel Gordziejonok, Selina Zoë Haack, MohammadAli Hamidi, Franz Albert Heinrichs, Hermann Hellwagner, Manuel Hoi, Tariqul Islam, Lend Jakupi, Hyewon Jeong, Al·lodi Jutglà Serrat, Luka Kaiser, Georg Kelih, Andreas Kogler, Leon Kordasch, Jonas Kurath, Armin Lachini, Gregor Lammer, David Langmeier, Halime Lezi, Sandro Linder, Daniele Lorenzi, Vignesh V Menon, Sabrina Muhrer, Pranusha Munjuluru, Minh Nguyen, Engin Orhan, Moritz Pecher, Theresa Petschenig, Timo Pfeifer, Leon Prüller, Gabriel Puri, Lingfeng Qu, Kamran Qureshi, Samuel Radler, Raimund Schatz, Yixin Shen, Yahor Siarheyeu, Mykyta Skipenko, Jameson Steiner, Babak Taraghi, Farzad Tashtarian, Per-Luca Thalmann, Leonardo Tocci, Julius van Dillen, Yiying Wei, Yuan Yuan, and Fabio Zinner. Thanks also to the ITEC support staff Martina Steinbacher, Verena Stranner, Nina Stiller, Margit Letter, Marion Taschwer, and Rudolf Messner, and to our international collaborators.

Finally, a big thank you to Bitmovin for seven years of trust and close collaboration, and to the Christian Doppler Research Association for its continuous support and the reviewers for their constructive feedback over the years!
Posted in ATHENA, News | Comments Off on Seven Years of ATHENA: Concluding the Christian Doppler Laboratory

3D Gaussian Splatting Rendering Performance Trade-offs on the Meta Quest 3

3D Gaussian Splatting Rendering Performance Trade-offs on the Meta Quest 3

IEEE International Conference on Visual Communications and Image Processing (VCIP 2026)

December 13 – December 16, 2026

Singapore

[PDF]

Milad Ghanbari (AAU, Austria), Hadi Amirpour (AAU, Austria), Christian Timmerer (AAU, Austria)

Abstract: 3D Gaussian Splatting (3DGS) is a compelling technique for real-time view synthesis, but its computational demands pose significant challenges for deployment on resource-constrained standalone eXtended Reality (XR) headsets. This paper presents a systematic performance study of 3DGS rendering on the Meta Quest 3, using a custom interactive tool that enables real-time control of render resolution scale, splat density, and frame rate cap through an in-world interface. We evaluate 180 conditions formed by the factorial combination of six resolution scales (0.5–1.0), ten splat density levels (10–100%), and three camera-to-object distances (0.7 m, 1.1 m, 1.5 m), with each condition repeated ten times. Performance metrics — GPU time, frame rate, GPU utilization, CPU utilization, power draw, and stale frame count — are captured via Meta’s Oculus Virtual Reality (OVR) Metrics Tool at a fixed target frame rate of 72 Hz. The results show that resolution scale is the dominant GPU cost driver due to the quadratic growth in pixel count, while splat density reduction is only an effective performance lever when GPU time is already close to the 72 Hz frame budget. Power draw is determined by total GPU work per time unit rather than cost per frame, which creates a counterintuitive relationship where lower resolution scales draw more power by enabling higher frame rates. These findings expose the interdependence between resolution scale, splat density, frame rate, and power, and establish a quantitative foundation for rendering parameter selection in 3DGS applications on standalone XR hardware.

Posted in ATHENA | Comments Off on 3D Gaussian Splatting Rendering Performance Trade-offs on the Meta Quest 3

Bitrate Ladder Analysis for UHD Adaptive Streaming: From AVC to AV2

Bitrate Ladder Analysis for UHD Adaptive Streaming: From AVC to AV2

IEEE International Conference on Visual Communications and Image Processing (VCIP 2026)

December 13 – December 16, 2026

Singapore

[PDF]

Kamran Qureshi (AAU, Austria), Hadi Amirpour (AAU, Austria), Christian Timmerer (AAU, Austria)

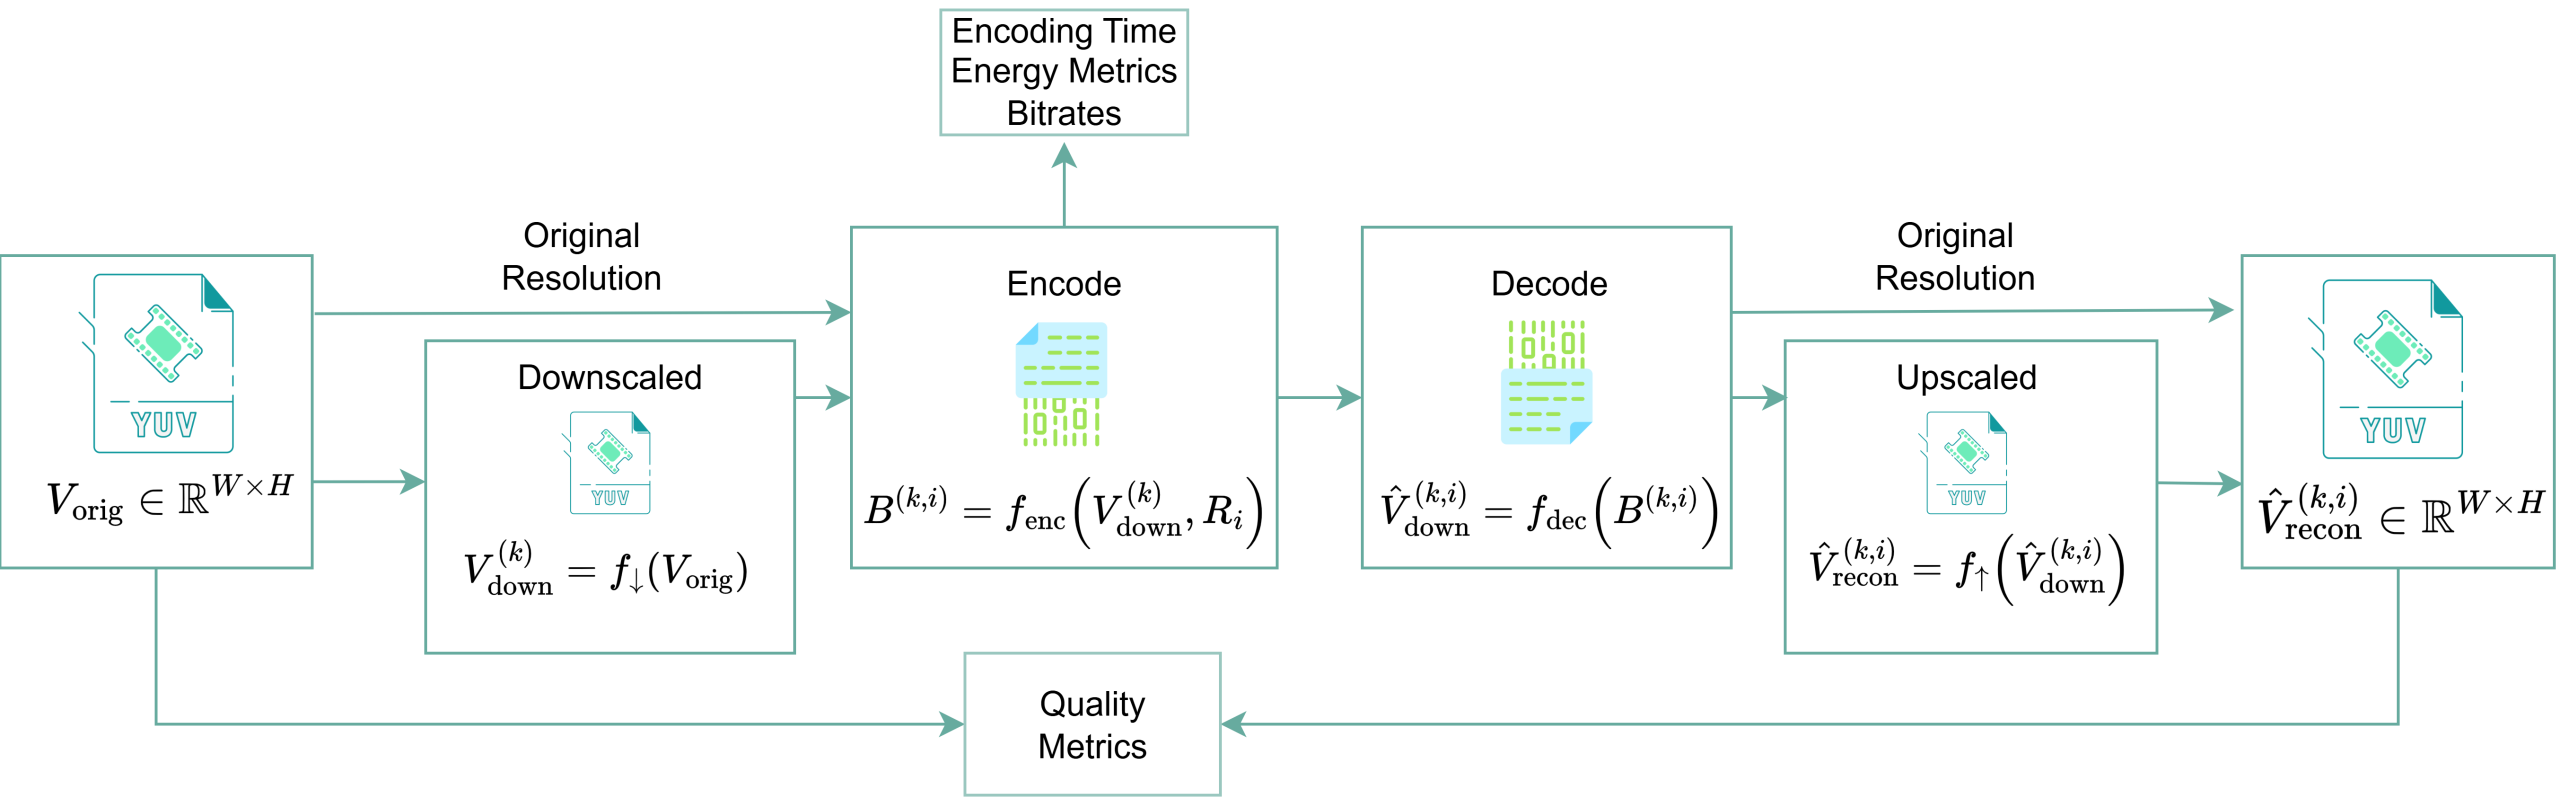
Abstract: Advances in video coding continue to improve compression efficiency for adaptive bitrate (ABR) streaming. However, improved coding efficiency also changes the rate-distortion characteristics of encoded video, thereby altering the resolution transition points and the resulting bitrate ladder for UHD adaptive streaming. A convex-hull-based evaluation was performed to compare codec-dependent bitrate ladders across H.264/AVC, H.265/HEVC, H.266/VVC, AV1, and AV2 using six UHD sequences from the JVET Common Test Conditions. Experimental results showed that higher codec efficiency systematically shifts resolution transition points toward lower bitrates. Relative to AV1, AV2 reduced the median 2160p-1080p transition bitrate by approximately 3x, while the median 1080p-720p and 720p-540p transition bitrates were approximately 9x lower, allowing higher spatial resolutions to remain optimal over a wider bitrate range. Complexity analysis of the evaluated AVC, HEVC, VVC, and AV1 encoders further showed that improved compression efficiency is accompanied by increased encoding time and energy consumption. These findings demonstrate that advances in video compression influence adaptive streaming by modifying the optimal bitrate ladder rather than simply reducing bitrate requirements.

Posted in ATHENA | Comments Off on Bitrate Ladder Analysis for UHD Adaptive Streaming: From AVC to AV2

Efficient Quality Controller for Video Encoding

Efficient Quality Controller for Video Encoding

IEEE Visual Communications and Image Processing Conference (VCIP 2026)

December 13–16, 2026

Singapore

[PDF]

Yiying Wei (AAU, Austria), Hadi Amirpour (AAU, Austria),  and Christian Timmerer (AAU, Austria)

Abstract: Traditional video streaming relies on Adaptive Bitrate (ABR) algorithms that encode videos at fixed bitrate-resolution pairs. As a result, a rate controller is essential to ensure that each encoded representation meets its target bitrate. However, perceptually-aware bitrate ladder construction methods aim to encode videos at a fixed visual quality instead of a fixed bitrate, to avoid under- or over-allocating bits for complex and simple content. In this paper, we propose an efficient quality controller that predicts the Quantization Parameter (QP) required to achieve a target VMAF score for each video segment. The framework supports both CPU-only operation for low-complexity environments and GPU-accelerated inference for improved prediction accuracy. By leveraging content features and target quality levels, our model estimates appropriate QP values without requiring pre-encoding or tight integration with the encoder. For target VMAF scores of 94, 88, and 82, the CPU-only model achieves mean absolute errors (MAEs) of 1.05, 1.24, and 1.34, respectively, comparable to the state-of-the-art errors of 1.14, 1.27, and 1.31, while requiring only a fraction of the computational cost. The GPU-based model further reduces the MAEs to 0.50, 0.49, and 0.47, less than half of the state-of-the-art errors.

Posted in ATHENA | Comments Off on Efficient Quality Controller for Video Encoding

Cloud, Edge, or Split? Profiling Onboard and Split Vision-Language Model Deployment for Drone AI

Cloud, Edge, or Split? Profiling Onboard and Split Vision-Language Model Deployment for Drone AI

Zoha Azimi, Reza Farahani, Schahram Dustdar, Christian Timmerer

The 4th International Symposium on Edge Intelligence, Trustworthy and Decentralized Artificial Intelligence (iEDGE 2026)

October 27-30, 2026 – Paris, France

Vision-Language Models (VLMs) enable edge devices like unmanned aerial vehicles (UAVs) to interpret visual observations and reason about complex environments using natural-language instructions. However, their practical deployment remains challenging as onboard inference is constrained by limited computational, memory, and energy resources, whereas cloud-based inference introduces communication latency, bandwidth overhead, and dependence on network connectivity. To address these limitations, split computing offers a promising alternative by partitioning VLM inference between the resource-constrained UAVs and more capable remote servers. However, the performance trade-offs among fully onboard, cloud-based, and split-computing architectures for lightweight VLMs have not yet been systematically profiled. This paper benchmarks these three deployment paradigms using SmolVLM-256M as a representative lightweight VLM. We quantify their inference latency, computational resource utilization, communication overhead, and energy consumption across varying image resolutions and network conditions. Our results show that no deployment strategy is universally optimal; instead, the preferred strategy depends on the interaction between network conditions and input image resolution.

Posted in ATHENA | Comments Off on Cloud, Edge, or Split? Profiling Onboard and Split Vision-Language Model Deployment for Drone AI

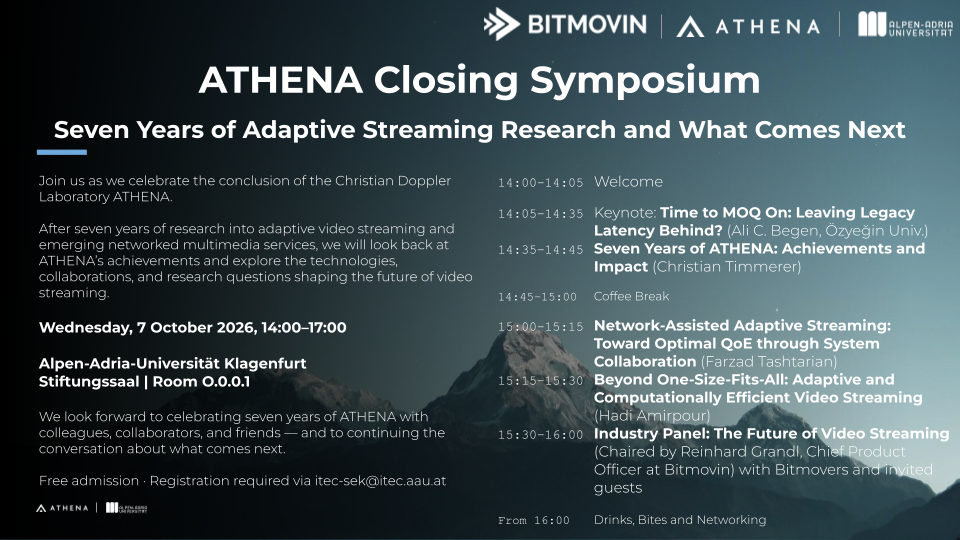
ATHENA Closing Symposium

Seven Years of Adaptive Streaming Research and What Comes Next

Join us as we celebrate the conclusion of the Christian Doppler Laboratory ATHENA [PDF)].

After seven years of research into adaptive video streaming and emerging networked multimedia services, we will look back at ATHENA’s achievements and explore the technologies, collaborations, and research questions shaping the future of video streaming.

Wednesday, 7 October 2026, 14:00–17:00
Alpen-Adria-Universität Klagenfurt, Stiftungssaal · Room O.0.0.1 [Slides]

Programme

14:00–14:05 · Welcome
14:05–14:35 · Keynote — Time to MOQ On: Leaving Legacy Latency Behind? (Ali C. Begen, Özyeğin University) [Slides]
14:35–14:45 · Seven Years of ATHENA: Achievements and Impact (Christian Timmerer) [Slides]
14:45–15:00 · Coffee Break
15:00–15:15 · Network-Assisted Adaptive Streaming: Toward Optimal QoE through System Collaboration (Farzad Tashtarian) [Slides]
15:15–15:30 · Beyond One-Size-Fits-All: Adaptive and Computationally Efficient Video Streaming (Hadi Amirpour) [Slides]
15:30–16:00 · Industry Panel: The Future of Video Streaming Chaired by Reinhard Grandl, Chief Product Officer at Bitmovin with Bitmovers and invited guests
From 16:00 · Drinks, Bites and Networking

We look forward to celebrating seven years of ATHENA with colleagues, collaborators, and friends — and to continuing the conversation about what comes next.

Free admission · Registration required via itec-sek@itec.aau.at

Posted in ATHENA | Comments Off on ATHENA Closing Symposium

Interns at ATHENA (Summer 2026)

Interns at ATHENA (Summer 2026)

In July 2026, the ATHENA Christian Doppler Laboratory hosted four interns working on the following topics:

  • Leon Kordasch – Holography
  • Daniel Glantschnig – Automated Wind Turbine Damage Detection
  • Gabriel Puri – Adaptive Streaming for Immersive Media

At the end of their internships, the interns presented their projects and findings and received official university certificates in recognition of their work. The experience proved valuable for both the interns and the ATHENA research team alike. Through personalized mentorship, hands-on training, and continuous support, the interns were able to develop strong practical skills while gaining a deeper understanding of research methodologies and technologies in the video streaming domain. We warmly thank the interns for their enthusiasm, dedication, and thoughtful feedback, which made a meaningful contribution to the ongoing work of the ATHENA lab.

Leon Kordasch: “During my internship, I worked on digital holography. I explored state-of-the-art solutions, analyzed their performance and gained lots of theoretical knowledge and technical experience. While challenging, the internship was very rewarding. My supervisor, Ayman Alkhateeb, provided guidance where needed, and collaborating with a diverse, international team made the experience both enriching and enjoyable.”

Daniel Glantschnig: “My time as an intern was both interesting and rewarding. I had the opportunity to train object detection models using datasets with and without synthetic data, then compare the results to explore how synthetic data influenced model performance. Working on this project helped me gain a much better understanding of dataset preparation, model training, evaluation, and the impact that different types of data can have on object detection systems. One of the highlights of the internship was the welcoming and friendly team, which made the experience even more enjoyable. I also greatly appreciated the support of my supervisor from the DORBINE project, Mario, who was always available to answer my questions and help me work through any challenges. The internship allowed me to apply my existing knowledge in a practical environment while developing new technical skills. Overall, I am very grateful for the opportunity, the guidance I received, and the valuable experience I gained during my time there.”

Gabriel Puri: “Over the past four weeks as an intern, I’ve had a wonderful experience. I had the opportunity to work on streaming immersive media to the Apple Vision Pro, and I even created a Swift application that streams spatial videos to a local server. This server processes the incoming stream using my integrated pipeline, which enables adaptive bitrate streaming. I’ve learned a lot about encoding and how it’s done in real-world applications such as Netflix streams. I’ve also learned through trial and error, for example by trying an approach and failing, but eventually succeeding. I also learned how to accurately grade video quality via AVQT. One of the most memorable aspects of the internship was undoubtedly the incredibly welcoming and inclusive team, as well as my supervisor and mentor, Kamran from the ATHENA project. He is a true expert in his field and provided me with crucial support. This internship has allowed me to apply my interest in computer science to useful real-world scenarios and gain industry insights. Overall, I am incredibly grateful for this opportunity and for all the guidance and support I received throughout the internship.“


Posted in ATHENA | Comments Off on Interns at ATHENA (Summer 2026)